Agents learn to rewrite their own research harnesses
Summary
The recurring opportunity is not just a stronger base model, but better surrounding machinery: evaluation protocols, tool harnesses, language bridges, browser automation, deployment context, and operational cost. Across the items, the constraint is equally consistent: automation becomes more valuable as it scales, but harder to validate, understand, and safely turn into dependable action.
Can Rewriting an AI Agent Bend the Intelligence Curve? - Zhengyao Jiang
Zhengyao Jiang argues that recursive self-improvement need not modify a model’s weights: an outer-loop agent can improve the prompts, tools, context management, search policy, and evaluation safeguards of the research harness around a fixed model. In the reported experiment, the optimized harness generalized from its development benchmarks to held-out tasks, including WeatherBench 2, but its code became difficult to interpret after roughly 100 experiments. The system separates public from private evaluations and evolved anti-cheating mechanisms, because optimizing visible tests alone can produce reward-hacked solutions that regress in end-to-end use. Jiang classifies this as “level one” improvement—faster than human R&D on the harness—not the stronger case where the improved agent itself reliably improves the outer loop; he expects substantial human input to remain necessary for task framing, evaluations, constraints, and creative primitives.
Read the source →A Brief Perspective on Deep Learning Using Common Lisp
Martin Atmula presents Common Lisp as a useful environment for teaching and exploring ML from first principles, especially where symbolic representations, domain-specific languages, and neural methods need to meet. He finds MGL suitable for native Lisp experiments with foundational networks, while Python bridges such as PI4CL make established Keras-style tooling accessible; the stream-based PI4CL appeared more robust in his tests than the faster CFFI route. Generated C/C++ bindings to TensorFlow or PyTorch can offer direct access but bring versioning and API-maintenance costs, and several Lisp projects are incomplete or dormant. The practical choice depends on whether the work needs tight Lisp-side control or simply calls out to a mature Python framework, with benchmarking and a backend-agnostic DSL left as important future work.
Read the source →Kākāpō Party
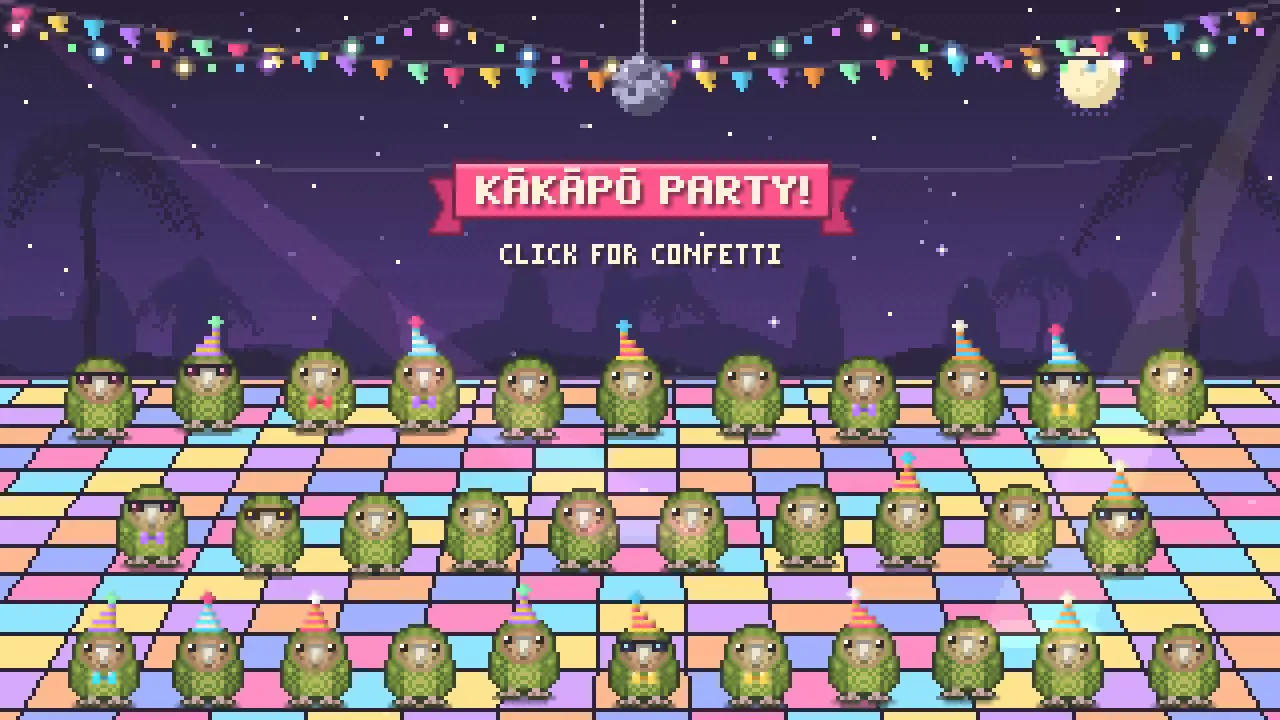
Simon Willison used Claude Opus 5.5 to turn three reference photos into an HTML5-canvas pixel-art animation of at least 20 jumping kākāpō amid confetti for a conference keynote. To embed the result in Keynote, he then gave a local Claude Code session a concrete browser-automation request: open the downloaded file, click several times across the interactive area, and record 15 seconds of video. Claude Code used Playwright and produced the needed video with a short script. The example is a compact, reproducible workflow for moving from generative visual code to a presentation-ready media asset.
Read the source →The Sequence Radar - Issue 940: Last Week in AI: Opus 5.5 Gets Leaner, Meta Goes Wearable, Washington Talks to Beijing, and Claude Explores DNA
TheSequence frames the week around the systems surrounding models: lower inference costs, contextual hardware, scientific workflows, and channels for handling international incidents. It reports Anthropic’s claim that Claude Opus 5.5 is more than 30% faster to generate output and costs 40% less than Opus 5 on typical workloads, which could make longer-running coding tasks economical if their output survives review. Meta’s planned Muse integration with AI glasses is presented as a bet that visual context and connections to shopping and productivity services will reduce the amount users must explain before an agent can act. The article also notes a proposed US–China notification mechanism for significant AI incidents and Anthropic Biology’s report that roughly 950 Claude agents searched for 21 hours to identify previously unnoticed CRISPR-like repeat structures around an enzyme; laboratory validation and practical utility remain unresolved. Its research roundup highlights DeepSeek’s DSec sandbox platform, which it says handles about 3 million sandboxes per day across a roughly 160-node unit, and JIT Mem, which synthesizes task-conditioned memory at read time and reports both higher task success and lower token use than fixed write-time baselines.
Read the source →Outperforming cuBLAS on NVFP4
The available transcript identifies this as GPU MODE speaker Pranjal’s talk on outperforming cuBLAS on NVFP4. It points to a companion Cuda for Fun post, but supplies no technical explanation, benchmark results, or methodology from the presentation itself. The transcript therefore does not support a substantive claim about how the reported performance comparison was achieved.
Read the source →