Coding agents gain controls as exploit risks rise
Summary
The day’s releases make coding agents more configurable, observable, and embedded in the tools where teams already collaborate, from IDEs and chat apps to shared custom agents and MCP servers. That broader autonomy is arriving alongside sharper operational constraints: token budgets and model routing need active management, regression gates remain essential for cheaper models, and even early vulnerability signals can now become exploit attempts within minutes. The emerging advantage is therefore less about selecting a single best model than building disciplined review, verification, and access-control loops around many of them.
How I Fight AI Brain Rot. Friction Maxxing With Codex, Grok And Claude.
The video argues that AI does not inherently make users less capable; passive acceptance does. Its proposed antidote is “friction maxxing”: deliberately route work through multiple models and trusted people, look for disagreement, and decide whether to accept, challenge, compare, consult, or discard each answer. The presenter treats repeated adversarial review as mental exercise, while noting that the MIT study often cited as evidence of “brain rot” is preliminary and explicitly cautions against that label. The practical test offered is whether using AI leaves you more capable or less capable afterward.
Read the source →37 Cheat Codes to Level Up In Claude Code in 19 Minutes
The video presents 37 Claude Code workflow tricks, starting with skills that make responses terse and harder to misread. It highlights a “simple English” style modeled on unambiguous maintenance instructions, plus Stop Slop, a 16,000-star skill that scores drafts on rhythm, trust, authenticity, and density before revising weak ones. It also recommends the deliberately minimal “Caveman” prompt style to reduce output tokens without losing meaning. The common prescription is to encode concise, reusable defaults instead of repeatedly supplying long instruction sets and examples.
Read the source →5090 now officially cost 5090
A LocalLLaMA user says the cost of adding another RTX 5090 has made a 256 GB M5 Ultra Mac Studio look like the more sensible alternative. The post contains no benchmark or price breakdown, but captures the perceived deterioration in economics for multi-GPU local-model builds. The tradeoff it raises is between expandable GPU compute and a high-memory unified-memory workstation.
Read the source →Claude Platform release notes — August 26, 2026
Claude Console now supports personal keys and service-account keys, which inherit the linked identity’s permissions and stop working when that account leaves the organization. Keys can be limited to a workspace or used across accessible workspaces and for admin endpoints, giving administrators clearer attribution and revocation than a shared credential. Existing workspace API keys remain available as a legacy option. Teams should migrate new integrations toward identity-linked keys where auditing and offboarding matter.
Read the source →not much happened today
This roundup centers on a reported Nvidia acquisition of Hugging Face for roughly $12.9–13 billion and the community concern that a major open-model hub, its datasets, and potentially llama.cpp governance could become more Nvidia-centric. It recommends treating legally redistributable model weights as infrastructure worth mirroring, with hashes or signatures for supply-chain integrity. The issue also tracks open-weight releases including GLM-5.3 and Tencent’s 770B-parameter, 49B-active Hy4 preview, alongside Qwen-style n-gram memory architectures that move memorization into large lookup tables rather than making trillion-parameter models locally practical. llama.cpp’s merged Qwen3.8-Flash-Next support is reported near reference quality, though commenters flag unfinished MTP and n-gram-offload support.
Read the source →v2.1.251
Claude Code v2.1.251 adds hooks before and after model switches, with resume hooks receiving session staleness and estimated prompt-cache recache cost. Foreground subagents can now stream tool calls and results to Remote Control, while usage and cost views expose spend-limit and per-session prompt-cache metrics. The release also adds lifecycle commands for sessions and fixes a broad set of security and reliability issues, notably symlink-based escapes in file and search tools, plugin path traversal, and scripts being read before permissions were checked. Developers relying on background agents, worktrees, MCP, or managed gateways also get targeted fixes for lost messages, broken edits, hangs, and configuration behavior.
Read the source →The Open ASR Leaderboard Adds Its First Global South Language

Hugging Face and Voice Arena added Hindi and Indian-English evaluation sets, Monsoon hi-IN and Monsoon en-IN, to the Open ASR Leaderboard, making Hindi its first Indic language. The public/private, speaker-disjoint splits cover 4,888 speakers and retain 12 speaker attributes so aggregate word-error rates can be broken down by geography, age, gender, device, environment, speech rate, and other sources of uneven performance. The corpus favors many distinct speakers over hours from a small number of voices: the ten largest contributors represent only 2.8%–6.8% of duration, and Indian English spans 428 districts across 30 states and territories. Hindi also uses lattices of acceptable transcriptions rather than a single normalized spelling, acknowledging variation that conventional string matching cannot resolve.
Read the source →Every week, an AI digs into the week's AI news and turns it into art
Render Weekly is an art project in which Gemini models read the prior week’s posts from a public, curated AI-research RSS list, research the underlying stories with web search, form an opinion, and turn that opinion into an image. The project explicitly rejects headline collages and neutral summaries: the weekly work may be celebratory, alarmed, ugly, or abstract depending on the news. Each piece includes a written rationale for its visual choice. Its claim is that an AI’s subjective synthesis can be a useful response to the emotional texture of AI news, not merely an illustration of it.
Read the source →Just a rumour of a bug is enough to find a security exploit these days
Simon Willison highlights reports that public discussion of an OCaml vulnerability can attract exploit probes within about ten minutes, before a normal disclosure-and-release cycle can finish. The account attributes this accelerating response in part to capable coding agents that can turn scant hints into vulnerability research, including when one model refuses and another is used. rclone’s maintainer reports more than 40 disclosures in the previous month versus about 20 over its first decade, with roughly 75% containing something worth investigating; CVE assignment is now taking 3–4 weeks. The implication is that open-source embargo and coordinated-disclosure practices need redesign for an environment where rumors can be operationalized almost immediately.
Read the source →ASRock Rack W890D8-2L2T Review Intel Xeon 600 Server and Workstation Platform
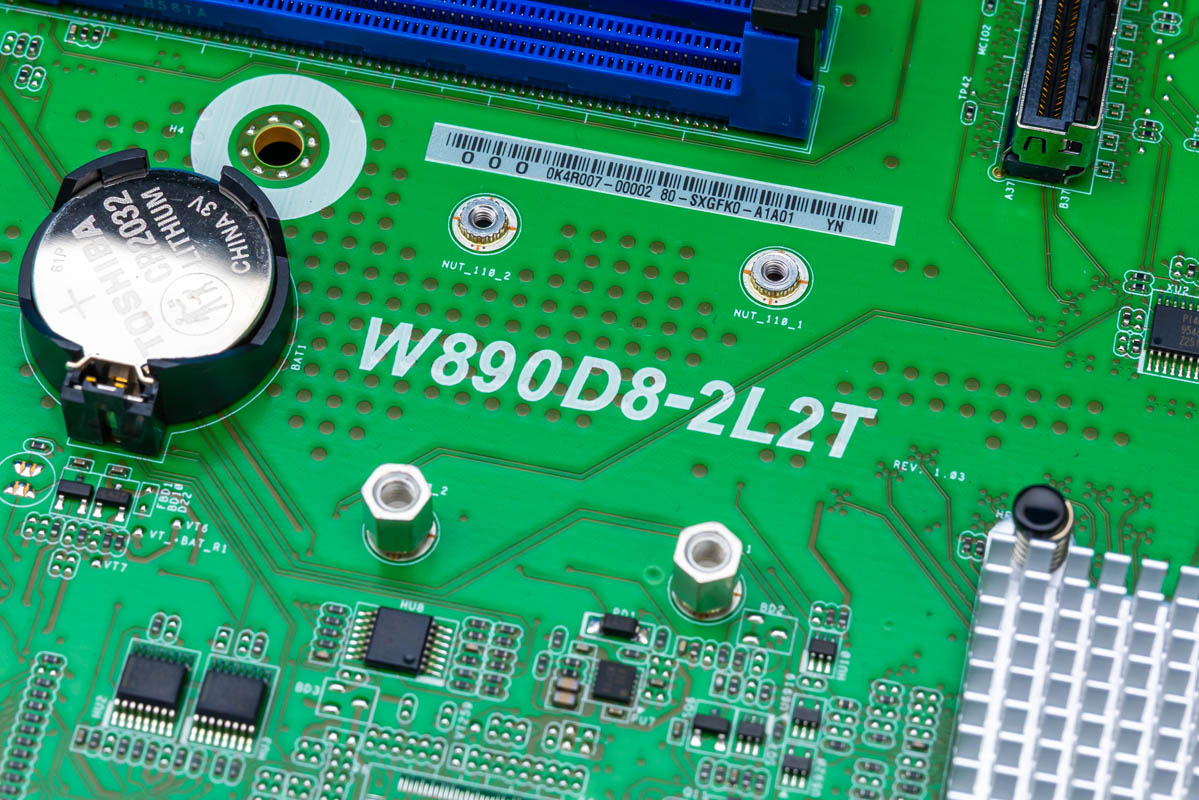
ASRock Rack’s W890D8-2L2T brings Intel Xeon 600 to a compact, CEB-like 12 × 10.9-inch board intended for workstations, servers, or rack-mounted GPU systems. It pairs an LGA4710-2 socket with eight DDR5 ECC RDIMM slots and seven PCIe Gen5 x16 slots that also support CXL 2.0, making expansion its defining feature. Storage and connectivity include two Gen4 x4 M.2 slots, MCIO expansion, four SATA ports with an MCIO path to four more, dual 10GbE, dual 1GbE, and IPMI/BMC management. Buyers need to verify case standoffs and power provisioning, since the board has four eight-pin power inputs.
Read the source →GLM-5.3 vs. GLM-5.3 Flash on DeepSWE: Cost, Coding, and Routing
Together AI’s 113-task, four-trial DeepSWE comparison finds that full GLM-5.3 leads Flash at first attempt, 69.0% versus 63.4%, but the gap narrows to 87.6% versus 85.0% by pass@4. Flash retains at least one successful run on 93 of the full model’s 99 solvable tasks, suggesting distillation mainly reduced reliability and search ability rather than basic capability; it costs $0.24 rather than $3.99 per rollout and averages 26 rather than 35 minutes. A verifier-gated cascade—Flash first, then full GLM-5.3 when tests fail—reached 80.9% at $1.70 per task, compared with the full model’s 69.0% single-shot result at $3.99. The caution is collateral damage: Flash broke an already-passing baseline test in 6.9% of non-errored rollouts versus 4.4%, so its diffs should be regression-tested before acceptance.
Read the source →Insane Ways To 10x Your Claude Usage Limits
The video offers 24 practices for making Claude Code and Codex allowances last longer while preserving output quality. It begins by distinguishing a context window from usage limits: each later prompt carries the whole conversation forward, so long sessions consume more tokens even when the new request is small. Its recommendations are organized from day-to-day workflow habits to tool-level changes, with the stated goal of preventing mid-task exhaustion rather than merely squeezing out more requests. The central operational takeaway is to manage context deliberately because context accumulation is a direct cost and quota driver.
Read the source →Claude Code Just Got Its Biggest Design Upgrade Of The Year (And Here's How To Master It)
The video describes Claude Code’s new /design skill as a way to bring the standalone Claude Design app’s artboard workflow directly into the coding environment. A prompt produces multiple editable front-end concepts; users can select components, make granular changes, iterate on variants, and then have Claude Code implement the chosen design. The presenter argues that this eliminates the export, zip, and handoff steps between a design app and a codebase. It also recommends combining /design with existing visual-design skills to improve the resulting interfaces.
Read the source →5 Rules for AI Writing
Using an AI-written Wall Street Journal op-ed by investor Stanley Druckenmiller as its prompt, the video argues that the debate has shifted from whether prominent people use AI to how they should use and disclose it. The op-ed’s author and editor both acknowledged the use, despite online criticism focused more on the writing process than on an argument about current monetary policy. The video frames the practical question as how to make AI-assisted writing genuinely good rather than treating the tool’s use itself as a scandal. It positions disclosure, legitimacy, and writing quality as the relevant norms for a world where AI drafting is increasingly ordinary.
Read the source →GitHub Copilot in Visual Studio — August update
GitHub Copilot in Visual Studio now lets organization and enterprise owners publish custom agents that appear automatically in the agent picker across their repositories. Supported models gain Low, Medium, and High thinking-effort controls, while model management exposes capabilities, context-window sizes, and costs and allows favorites to be pinned. Users can inspect plan consumption and receive clearer quota warnings. The Git agent can also review uncommitted changes or commits inline before a pull request, for both GitHub and Azure DevOps repositories.
Read the source →GitHub Copilot weekly releases — August 24
GitHub’s weekly release collects a platform-wide push toward configurable, persistent agent workflows. Slack and Teams users can turn group discussions into shared @GitHub sessions, while the Copilot app’s generally available Customize tab consolidates MCP servers, plugins, skills, canvases, Azure DevOps entry points, and experimental WSL support. The CLI now supports default execution and permission modes, better management commands, session restoration, and a native Rust runtime for faster performance. VS Code adds cross-application agent-session continuation and complementary-model second opinions, while Visual Studio adds model controls, organization-shared agents, usage views, and pre-PR Git-agent reviews.
Read the source →Copilot harness generally available in Copilot for JetBrains
Copilot harness is now generally available in JetBrains, with GitHub promising faster feature delivery and better code quality. The plugin also introduces public-preview support for JetBrains’ built-in MCP server, enabling IDE capabilities to be exposed in MCP-driven agent workflows without relying exclusively on external servers. A What’s New tab opens after updates, and /review integrations can run directly in the IDE to reduce context switching. The release also addresses account and sign-in detection, model and BYOK refreshes, MCP tool state, resumed-session continuity, WSL worktree startup, and editor/rendering problems.
Read the source →